<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://joelchrono.xyz/feeds/rss.xml" rel="self" type="application/atom+xml" /><link href="https://joelchrono.xyz/" rel="alternate" type="text/html" /><updated>2026-10-14T17:14:05-06:00</updated><id>https://joelchrono.xyz/feeds/rss.xml</id><title type="html">joelchrono’s blog</title><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><entry><title type="html">What Interested Me Today 8</title><link href="https://joelchrono.xyz/blog/what-interested-me-today-8/" rel="alternate" type="text/html" title="What Interested Me Today 8" /><published>2026-04-15T18:30:00-06:00</published><updated>2026-04-15T18:30:00-06:00</updated><id>https://joelchrono.xyz/blog/what-interested-me-today-8</id><content type="html" xml:base="https://joelchrono.xyz/blog/what-interested-me-today-8/"><![CDATA[<figure class="img">
  <picture>
    <source srcset="/assets/img/blogs/2026-04-15-interests.webp" type="image/webp" />
    <source srcset="/assets/img/blogs/2026-04-15-interests.webp" />
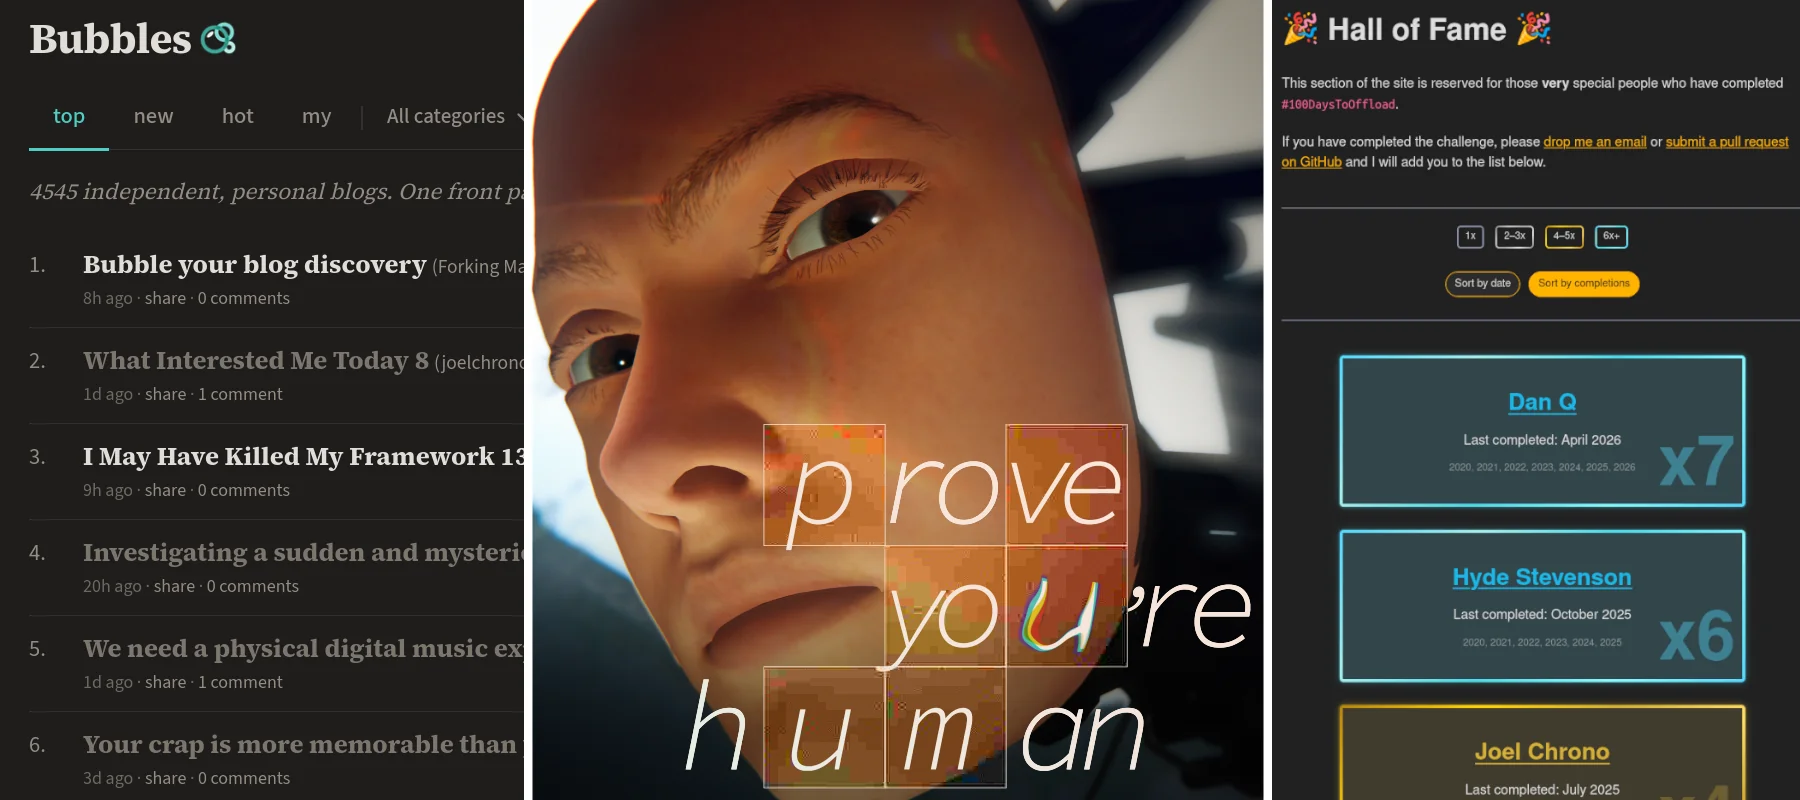
    <img class="mx-auto" src="/assets/img/blogs/2026-04-15-interests.webp" alt="screenshots of the interests mentioned in the text" />
  </picture>
  <figcaption class="caption">Bubbles main page, art of the game, and the 100DaysToOffload hall of fame</figcaption></figure>

<p>Welcome to another installment of “things that interested me today but aren’t enough to warrant a blogpost by themselves so I bundled them all together here”—I hope you find something that catches your eye!</p>

<p>Again I don’t really plan to do these every week but it just so happens that I felt like writing about something but didn’t really have a big topic in mind.</p>

<p>Oh well, enjoy the links!</p>

<h2 id="bubbles-a-frontpage-for-the-indieweb">Bubbles, a frontpage for the IndieWeb</h2>

<p><a href="https://moddedbear.com/bubbles-is-the-cool-new-way-to-find-blogs/">Jeremy mentioned a new site</a> that serves as a blog discovery platform: <a href="https://bubbles.town">Bubbles</a>!</p>

<p>It looks rather simple, very similar to Reddit, Lemmy, Hacker News or Lobste.rs. However, this is not about tech articles or about whatever drives the most clicks, it’s a platform to surface bloggers, people writing about their lives and whatever they want.</p>

<p>They seem to be really focused on the IndieWeb, and even provide a widget that can be added to your website so the upvotes you get there can be seen on your posts. That’s kind of fun!</p>

<p>You even log-in with your fediverse account, it doesn’t have to be just Mastodon either, so that’s pretty awesome. No extra account setup, no email to give, all good for me.</p>

<p>The way comments work is based on the same principle, leave a comment on a mastodon post generated by Bubbles itself using your Fediverse client, and it will appear in bubbles too—similar to how <a href="/blog/how-to-add-mastodon-comments-to-jekyll-blog/">my comments system works</a>.</p>

<h2 id="prove-youre-human-from-the-creators-of-1000xresist"><em>Prove You’re Human</em>, from the creators of <em>1000xRESIST</em></h2>

<p>If you don’t know, <a href="/blog/1000xRESIST/">1000xRESIST</a> is the most unique experience I’ve ever had in gaming, and in my top 5 favourite games of all time.</p>

<p><a href="https://www.sunsetvisitor.studio/">Sunset Visitor</a> is the studio behind this masterpiece, and now they’re working on a new project!</p>

<p>Featuring captcha solving, living in the Windows XP wallpaper, and some strange robot with a face attached to it. This seems to be a very interesting take which will have a couple things to say about AI. Here’s the summary!</p>

<blockquote>
  <p>Prove You’re Human is a sci-fi narrative adventure in which you play as Santana and split your consciousness in two. The company behind this program has a chance at achieving true AGI — but there’s just one problem.</p>

  <p>The company’s AI, Mesa, believes she’s a human being. It’s your job to train her out of these delusions.</p>
</blockquote>

<p>Even though AI in real life right is an <a href="/blog/unpolished-human-websites/">absolute</a> <a href="/blog/not-having-to-work-would-be-nice-but-not-like-this/">pain</a>, and I don’t like hearing much about what it, this game, from this studio, gets a pass, and I’m sure it will have a lot to say about things and I am looking forward to it.</p>

<h2 id="im-in-the-podium-of-100daystooffload">I’m in the podium of #100DaysToOffload</h2>

<p>I’ve talked about this <a href="https://100daystooffload.com/">100 DaysToOffload challenge</a> before—and Kev, who keeps the website updated with the people participating in it—<a href="https://fosstodon.org/@kev/116386572668321193">recently changed the design a bit!</a></p>

<p>There’s now a button to sort by number of completions, and I am happy to say that I am in the top 3!</p>

<p>Unfortunately for me, <a href="https://lazybea.rs">Hyde</a> surpasses me by two and <a href="https://danq.me/">Dan Q</a> sits at the throne with a total of 7 completions!</p>

<p>Honestly though I am relieved that <a href="https://www.rubenerd.au/">Rubenerd</a>—who recently updated his URL btw so update it if you haven’t —has not participated on it. He doesn’t need to anyway… <em>Please, if you read this, please don’t do it I beg you!!</em></p>

<h2 id="more-blogs-for-my-rss-reader">More blogs for my RSS reader…</h2>

<ul>
  <li>
    <p><a href="https://theretrodad.blogspot.com/">The Retro Dad</a> - Brandon mentioned this post while talking about <a href="https://brandons-journal.com/post/skilcraft-government-pens">Skilcraft Government Pens</a>—of all things—and the name was eye-catching enough. Even more so when I realized it’s a BlogSpot site! The design is nice enough and the posts seem right up my alley as well, so yeah, check it out!</p>
  </li>
  <li>
    <p><a href="https://artlung.com/">Joe Crawford</a> - I met Joe during an IndieWeb online meeting! He organizes them every week—there will be one in the very same day this post is published—and has been around for a long while so, yeah, I just had to have him on my feed.</p>
  </li>
  <li>
    <p><a href="https://stitching.bearblog.dev/recognizing-feelings-of-burnout/">Stitching</a> - I found this small bearblog site from one of <a href="https://robertbirming.com/every-post-perfect/">Robert Birming’s posts</a>, and I enjoyed the posts there are, I am looking forward to seeing more! Some of the posts I’ve seen so far are book reviews, collecting CDs and physical books and stuff about life. I see in their <a href="https://stitching.bearblog.dev/currently/">now page</a> that Persona 5 Royal is being played, so that’s cool too.</p>
  </li>
</ul>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="rss" /><category term="fediverse" /><category term="podcasts" /><category term="software" /><category term="gaming" /><summary type="html"><![CDATA[Just another post with links and things that caught my interest lately.]]></summary></entry><entry><title type="html">What Interested Me Today 7</title><link href="https://joelchrono.xyz/blog/what-interested-me-today-7/" rel="alternate" type="text/html" title="What Interested Me Today 7" /><published>2026-04-10T09:40:00-06:00</published><updated>2026-04-10T09:40:00-06:00</updated><id>https://joelchrono.xyz/blog/what-interested-me-today-7</id><content type="html" xml:base="https://joelchrono.xyz/blog/what-interested-me-today-7/"><![CDATA[<p>I am currently working on my review for <em>Resident Evil</em>, but I need to take some pictures and finish it up a little more! So far I tend to separate everything into the basics, art, gameplay, story, music and stuff; but I ended up turning this post into more of a retrospective about survival horror as a whole and bringing up the Romero movies and talking about the FMVs and other things and, basically it’s a work in progress and the kind of thing I could make into a video essay if I put more effort into it, so it’s not ready.</p>

<p>For now, this is a quick post about <strong>what interested me today!</strong> I have been thinking about renaming this not-very-official—since it doesn’t even have a tag yet—series, to include what’s actually in it—similar to how my weeknotes are not just titled “Weeknotes”, more like Andreas’ <a href="https://82mhz.net/posts/#Linkdumps">Linkdumps</a>, I guess this is the same thing.</p>

<h2 id="some-blogs-i-added-to-my-rss-feed">Some blogs I added to my RSS feed</h2>

<ul>
  <li>
    <p>I have followed and enjoyed <a href="https://brandons-journal.com">Brandon’s Journal</a> for a while, but during a short hiatus where he took it down, I ended up removing it from my FreshRSS feed. I realized when he returned months ago, but I forgot to add him back, that mistake has been corrected. Here’s a <a href="https://brandons-journal.com/post/just-write">short post</a> to get a taste for his writing!</p>
  </li>
  <li>
    <p><a href="https://chameth.com/">Chris Smith’s</a> website was not on my radar at all, but I often like to check who links back to me and noticed that he mentioned me on his <a href="https://chameth.com/monthly-meanderings-2026-03/">monthly meanderings</a>, where he appreciated the way I link back to posts I reply to, etc. In any case, I really liked the design and the fact he has a section for all his <a href="https://chameth.com/boardgames/">board games</a>.</p>
  </li>
  <li>
    <p>Last but not least! <a href="https://marmar22.tilde.team/">marmar22</a> was a fun find. I can’t recall where I found their site, I believe I was just looking for some ereader blogposts somewhere because I stumbled upon <a href="https://marmar22.tilde.team/blog/a-review-of-a-cheap-e-reader-because-i-bought-one.html">this review</a> of some no brand ereader. The posts about <a href="https://marmar22.tilde.team/blog/organising-my-photos.html">organising photos</a> felt kind of familiar as well.</p>
  </li>
</ul>

<p>So yeah! I won’t say I’ll read everything but it’s always fun to have more variety. As I write this there are 6689 unread articles on my FreshRSS instance…</p>

<h2 id="a-dumb-web-fediverse-client">A dumb web fediverse client</h2>

<p>There are a lot of clients for the fediverse, from apps to terminals to web clients. Personally I mostly stick to the default web interface and to <a href="https://tusky.app">Tusky</a> on my phone.</p>

<p>But <a href="https://social.pollux.casa/@adele">Adele</a> recently created a minimal web client that doesn’t rely on javascript and can run on ancient browsers and devices! She wrote a <a href="https://adele.pages.casa/md/blog/the-fediverse-deserves-a-dumb-graphical-client.md">blogpost announcing it</a>.</p>

<h2 id="into-the-aethers-latest-bonus-episode">Into The Aether’s latest bonus episode!</h2>

<p>I you like the <strong>Persona</strong> games, you may be up to listening to a 5+ hours long deep dive into <a href="https://intothecast.transistor.fm/episodes/persona-4-golden-bonus-episode"><em>Personal 4 Golden</em></a>, treat yourself and get into my favorite podcast of all time!</p>

<p>Personally, I’m skipping it until I play that series, more than happy to listen to their weekly episode, the <a href="https://intothecast.transistor.fm/episodes/daruni-os-they-rock-feat-zelda-ocarina-of-time-fire-emblem-advance-wars-and-cairn">latest</a> of which also talks about the rumours around a remake of <em>The Legend of Zelda: Ocarina of Time</em> for the Nintendo Switch 2. This may make me buy that console at last, no doubt.</p>

<h2 id="linux-user-groups-and-updating-my-xteink-x4">Linux user groups and updating my XTEINK X4</h2>

<p>I noticed that <a href="https://github.com/crosspoint-reader/crosspoint-reader">Crosspoint</a>, the firmware I use on my <a href="/blog/early-days-with-xteink-x4/">XTEINK X4</a> recently had an update to 1.2 which introduced a couple features like a built-in EPUB optimizer, a way to turn text in current page to a QR code, and other goodies.</p>

<p>Last time I mentioned how I had to use my dad’s laptop to flash the firmware due to missing permissions. This time I took the time to figure things out and realized that I simply had to add my user to the <code class="language-plaintext highlighter-rouge">uucp</code> linux group. After restarting my user session things went smoothly from there! A shame I need to use Chromium to run the <a href="https://xteink.dev.al">web installer</a> though.</p>

<h2 id="another-ttrpg-bundle">Another TTRPG bundle…</h2>

<p>There’s a <a href="https://www.humblebundle.com/books/pathfinder-second-edition-bundle-at-center-world-paizo-inc-books">Pathfinder Humble Bundle</a> going on right now and my TTRPG friends are making me consider it yet again. I haven’t even had a second session of <em>Land of Eem</em> yet, but things happen.</p>

<p>In any case, this bit is just to let you know, and tempt you to get it as well.</p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="rss" /><category term="fediverse" /><category term="podcasts" /><category term="software" /><category term="gaming" /><summary type="html"><![CDATA[Just another post with links and things that caught my interest lately.]]></summary></entry><entry><title type="html">Using FreshRSS User Queries to keep up with your websites!</title><link href="https://joelchrono.xyz/blog/using-freshrss-user-queries/" rel="alternate" type="text/html" title="Using FreshRSS User Queries to keep up with your websites!" /><published>2025-07-30T08:10:00-06:00</published><updated>2025-07-30T08:10:00-06:00</updated><id>https://joelchrono.xyz/blog/freshrss-user-queries</id><content type="html" xml:base="https://joelchrono.xyz/blog/using-freshrss-user-queries/"><![CDATA[<p>I love using RSS to keep up with the bloggers out there! and I follow a lot of writers that share stuff in their websites quite regularly, but sometimes it can be a bit of a pain.</p>

<p>This is the case with Week Notes. I love them! And I follow a lot of people writing them consistently, some just call them “Week Notes”, some go for “Weekly Rewind” and I’m sure there are some people out there doing their own thing, such as how I recently went for titling them differently and just adding the week number at the end.</p>

<p>The point is, it’s a bit of a struggle to get them all in one single place!</p>

<p>Here is where <a href="https://freshrss.org">FreshRSS</a> comes to the rescue once again.</p>

<p>I have used and written about many of its features before, such as <a href="/blog/word-filters">word filters</a> and <a href="/blog/newsboat-queries-and-freshrss-scraping">website scraping</a>, and even after all this time, it still manages to surprise me whenever I dive into its feature set once more.</p>

<p>User Queries are like word filters, but in the opposite direction. It is basically a bookmarked search term, that you can easily access in the web interface with a couple of clicks.</p>

<p>Unfortunately, I don’t think there’s any 3rd party client that can use this feature, but given that 99% of my usage is actually done on a computer, I can’t really complain. Besides, Newsboat which is the terminal client I use on Linux, can probably replicate this, and if I ever get around to set that up, I’ll update this post.</p>

<p>To create a query in FreshRSS web frontend, you just need to click the bookmark 🔖 icon in the top row of the main UI, and click on “Bookmark Current Query”, this will take you to the User Queries settings page, where you can click the cogwheel to customize the behavior. Give it a name, description, image, share the query as an RSS feed or OPML. And of course actually define the query itself.</p>

<p>For my usecase, I started with this query:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>intitle:week intitle:note
</code></pre></div></div>

<p>The usage of search parameters is explained on <a href="https://freshrss.github.io/FreshRSS/en/users/10_filter.html#with-the-search-field">FreshRSS’ Documentation</a>, but in short, having parameters separated by a space is basically an AND operation between them, you can also exclude keywords and even regular expressions with <code class="language-plaintext highlighter-rouge">-</code> or <code class="language-plaintext highlighter-rouge">!</code>.</p>

<p>After messing around for a bit more, I ended up with the following query:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>(author:gobino intitle:"weekly rewind") OR (intitle:week intitle:note) OR (intitle:"- W" author:joel)
</code></pre></div></div>

<p>Which takes into account the format preferred by <a href="https://gobino.be">Steven</a> and my own updated weeknote format where I use different titles but they all end with the week number (such as “W30”).</p>

<p>I have one or two queries for Monthly Summaries and also Link Blogs, so please let me know if you find other interesting ways to take advantage of them! Or if you don’t use FreshRSS, do you have a different solution for this problem?</p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="rss" /><category term="tutorial" /><category term="software" /><summary type="html"><![CDATA[FreshRSS is still my choice for a selfhosted RSS Reader solution. And User Queries, which have existed for a while, are yet another reason why!]]></summary></entry><entry><title type="html">Trying to organize my feeds</title><link href="https://joelchrono.xyz/blog/trying-to-organize-my-feeds/" rel="alternate" type="text/html" title="Trying to organize my feeds" /><published>2025-05-08T23:09:28-06:00</published><updated>2025-05-08T23:09:28-06:00</updated><id>https://joelchrono.xyz/blog/trying-to-organize-my-feeds</id><content type="html" xml:base="https://joelchrono.xyz/blog/trying-to-organize-my-feeds/"><![CDATA[<p>For a long time, I have been using the same set of categories for all of my feeds.</p>

<p>There are those for news, comics and project updates,  as well as one for Personal Websites.</p>

<p>Later on, I also created a category for all the websites doing <a href="https://100daystooffload.com">#100DaysToOffload</a>, like me.</p>

<p>This has been the case for 3 years.</p>

<p>What has not been the case for 3 years, is the quantity! The amount of blog posts I follow has grown by a lot. I am susbcribed to 250 websites, more or less, and I constantly adding more to the mix. There really are <a href="/blog/so-many-feeds-to-follow/">a lot of feeds to follow</a>.</p>

<p>Obviously, a couple of categories is not really sustainable anymore. Not everyone posts at the same rate, and sadly, I don’t have the time to read every single thing every single person I follow writes.</p>

<p>There’s also the problem of some bloggers writing with more frequency than others, with different levels of relevance as well.</p>

<p><a href="https://www.rubenerd.au">Ruben Schade</a> posts a lot of stuff at all times, which means he’ll show up much more regularly than <a href="https://flamedfury.com">Flamed</a> who doesn’t post that often.</p>

<p>There’s also <a href="https://dandelion-utilitarian.com">HexDSL</a> or <a href="https://eilloh.net">Hollie</a> who share micro-thoughts or drawings more than regular posts, which means that they have a lot of entries on their feeds, and even if they’re quick to read, they take more screen space than I’d like.</p>

<p>And of course, there are those bloggers that will take <em>ages</em> before they publish something, like <a href="https://hunden.linuxkompis.se">Hund</a> or <a href="https://analogoffice.net">Analog Office</a>, sometimes they share some absolute bangers, sometimes it’s a simple post catching up, letting us know they’re still around. Whatever the case, I don’t want to miss out!</p>

<p>Chatting with <a href="https://benjaminhollon.com">Amin</a>, he told me he has some categories based on how much he values the posts to read them later, be it weeks, or just a few days. He has Gold, Silver and Bronze!</p>

<p>He told me I am in the Silver category, so from now on my current goal is to achieve Gold status some day—the odds are against me though, because he has very high standards. 🥲</p>

<p>Anyway, I don’t think three categories is enough for the volume of blog posts I get every week. I could trim down the feeds, let go of some of them that I don’t follow that much. But that’s too easy.</p>

<p>I’ve created a few categories that I’ll try to improve over time, right now it’s something like this:</p>

<ul>
  <li>Blogging Friends: for people I interact with often, regardless of how often they post.</li>
  <li>Sporadic Bloggers: for those that really take a while to post stuff, I moved a couple friends here to not miss out on them.</li>
  <li>100DaysToOffload: People who are doing, or have completed the challenge already.</li>
  <li>Blogs in Spanish: I follow so few people writing in Spanish I just grouped them all. If you have recommendations let me know!</li>
  <li>TWG Discord: Members from the only Discord server I actually interact with, that also have blogs, kinda specific but it works.</li>
  <li>Reviewers: This one is kinda empty, but it’s pretty clear what it will contain, for games or books alike.</li>
</ul>

<p>I still have to actually move plenty of feeds around to the correct categories, but I think it’s a decent start. How do you guys do it?</p>

<p>This is day 63 of <a href="https://100daystooffload.com">#100DaysToOffload</a></p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="rss" /><category term="internet" /><category term="community" /><summary type="html"><![CDATA[They are all a mess right now]]></summary></entry><entry><title type="html">Rapberry Pi is out (for now)</title><link href="https://joelchrono.xyz/blog/rapberry-pi-is-out-(for-now)/" rel="alternate" type="text/html" title="Rapberry Pi is out (for now)" /><published>2024-09-17T05:23:40-06:00</published><updated>2024-09-17T05:23:40-06:00</updated><id>https://joelchrono.xyz/blog/rapberry-pi-is-out-(for-now)</id><content type="html" xml:base="https://joelchrono.xyz/blog/rapberry-pi-is-out-(for-now)/"><![CDATA[<p>So, a few days ago my Raspberry Pi died because of a power outage, most likely, the SD card got corrupted <em>again</em>.</p>

<p>I really, really should just look for some way to stop that from happening.</p>

<p>Anyway, my contact synchronization is no more, my FreshRSS instance is no more, my Nextcloud instance is no more, and I have to find alternatives in the mean time.</p>

<p>I think that I will for sure switch to an SSD next time I try to boot it up, I already have one that I just haven’t installed and should help me avoid these issues. these issues. Right now my Pi is just sitting there collecting dust, I actually bought a new mini hdmi dongle to try and boot it with a monitor and keyboard plugged in.</p>

<p>For a bit I even thought of going back to Google, but I am not that lazy. I will probablyl just trust <a href="https://disroot.org">Disroot</a> enough to hold my contact and calendar info, and maybe the <a href="https://rss.zdx.fr">ZDX free FreshRSS instance</a> to be my RSS backend.</p>

<p>Thankfully, all of the pictures I had on Nextcloud is on an external drive I was using as just storage on my Raspberry Pi, so I can still get that out. I could probably just keep using it as just a hard drive and use it whenever I need. I remember using MEGA at some point for my cloud storage needs, I should maybe go back to that? I dont’ know.</p>

<p>Everything would be solved if I just had some external power source that kept my Pi alive during outages, and a script that shut it down safely…</p>

<p>This is day of 71 <a href="https://100daystooffload.com">#100DaysToOffload</a></p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="raspberrypi" /><category term="selfhost" /><category term="rss" /><summary type="html"><![CDATA[My Raspberry Pi shutdown and won't come back online for a bit, so what now?]]></summary></entry><entry><title type="html">Improving my RSS feed</title><link href="https://joelchrono.xyz/blog/improving-my-rss-feed/" rel="alternate" type="text/html" title="Improving my RSS feed" /><published>2024-02-19T13:21:31-06:00</published><updated>2024-02-19T13:21:31-06:00</updated><id>https://joelchrono.xyz/blog/improving-my-rss-feed</id><content type="html" xml:base="https://joelchrono.xyz/blog/improving-my-rss-feed/"><![CDATA[<p>Playing around with Jekyll is great, or with any static site generator in general! But there can also be many ways to do things wrong! And while this is not really a problem most of the time, you could end up making a mess for your future self, like I’ve done this time.</p>

<p>However, I don’t see this as a failure, but as a way to keep improving myself, and something to write about in the process! So, I corrected the way I add a “reply via email (and fediverse) link” to each feed item, and also made my feed human-readable!</p>

<h1 id="adding-reply-via-email-and-fediverse-properly">Adding Reply via Email (and Fediverse!) properly</h1>

<p>Features such as includes and templates, can lead one towards the wrong path, and such was the case when I implemented email replies. I originally created an file in the <code class="language-plaintext highlighter-rouge">_include</code> folder, and I simply included it in every single article at the end, the contents of that file were hidden via CSS with <code class="language-plaintext highlighter-rouge">display:none</code>, it was a rushed and ugly way of doing this.</p>

<p>I decided to check what the rest of my friends were doing. And that’s where I noticed that in <a href="https://kevquirk.com">kevquirk.com</a>’s <a href="https://github.com/kevquirk/kq-jekyll/blob/main/feed.xml">source code</a> for its Jekyll version, the <code class="language-plaintext highlighter-rouge">feed.xml</code> file was simply, a customized feed template that included the reply via email button at the end. In his case, he escapes the XML and pasted it directly:</p>

<div class="language-xml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nt">&lt;description&gt;</span>
{{ post.content | xml_escape }}
<span class="ni">&amp;lt;</span>p style=<span class="ni">&amp;quot;</span>font-size:1.3rem<span class="ni">&amp;quot;&amp;gt;&amp;lt;</span>a href=<span class="ni">&amp;quot;</span>mailto:{{ site.email | xml_escape }}?subject={{ post.title | xml_escape }}<span class="ni">&amp;quot;&amp;gt;</span>Reply to this post via email<span class="ni">&amp;lt;</span>/a<span class="ni">&amp;gt;&amp;lt;</span>/p<span class="ni">&amp;gt;</span>
<span class="nt">&lt;/description&gt;</span>
</code></pre></div></div>

<p>I was using the <code class="language-plaintext highlighter-rouge">jekyll-feed</code> plugin for this, but I decided to change it for my own custom template too, but I am using the Atom format, instead of RSS 2.0. Since my current feed was using the Atom format, I didn’t want to break something by changing it too much.</p>

<p>As for the way I implemented the reply link, I went for a different—maybe more elegant—method, where I can still edit the proper HTML easily via an include, and capturing its output in a variable that I can then escape. Here is what it looks like:</p>

<div class="language-liquid highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&lt;content type="html" xml:base="<span class="cp">{{</span><span class="w"> </span><span class="nv">post</span><span class="p">.</span><span class="nv">url</span><span class="w"> </span><span class="p">|</span><span class="w"> </span><span class="nf">absolute_url</span><span class="w"> </span><span class="cp">}}</span>"&gt;
    <span class="cp">{{</span><span class="w"> </span><span class="nv">post</span><span class="p">.</span><span class="nv">content</span><span class="w"> </span><span class="p">|</span><span class="w"> </span><span class="nf">xml_escape</span><span class="w"> </span><span class="cp">}}</span>
    <span class="cp">{%</span><span class="w"> </span><span class="nt">capture</span><span class="w"> </span><span class="nv">replies</span><span class="w"> </span><span class="cp">%}{%</span><span class="w"> </span><span class="nt">include</span><span class="w"> </span>replies.html<span class="w"> </span><span class="cp">%}{%</span><span class="w"> </span><span class="nt">endcapture</span><span class="w"> </span><span class="cp">%}</span>
    <span class="cp">{{</span><span class="w"> </span><span class="nv">replies</span><span class="w"> </span><span class="p">|</span><span class="w"> </span><span class="nf">xml_escape</span><span class="w"> </span><span class="cp">}}</span>
&lt;/content&gt;
</code></pre></div></div>

<p>Now the end of every article contains a link to reply to it, just like on the website!</p>

<h1 id="customizing-the-look-of-my-rss-feed-with-xslt">Customizing the look of my RSS feed with XSLT</h1>

<p>Now, after doing the reply via email thing, I wasn’t feeling like only sharing a blogpost with one single website change that isn’t even that noticeable to begin with!</p>

<p>This is why I also decided to work on making my RSS feed <strong>human-readable</strong>, inspired by <a href="https://minutestomidnight.co.uk/blog/build-a-human-readable-rss-with-jekyll/">this post from Minutes to Midnight</a>—although I recall seeing this applied on some other people’s feeds—I finally went ahead and tried XSLT templating!</p>

<p>This was quite a great excercise, but it proved to be harder than expected given the fact that Simone Silvestroni used RSS 2.0 like Kev. Therefore, I couldn’t just copy and paste—I had to find out how to apply this to my Atom feed. After some research online, it wasn’t that difficult—here’s what my template looks like now:</p>

<div class="language-xml highlighter-rouge"><div class="highlight"><pre class="highlight"><code>---
layout: none
title: rss feed | joelchrono
permalink: "/feed.xsl"
---
<span class="cp">&lt;?xml version="1.0" encoding="utf-8"?&gt;</span>
<span class="nt">&lt;xsl:stylesheet</span> 
<span class="na">version=</span><span class="s">"1.0"</span> 
<span class="na">xmlns:xsl=</span><span class="s">"http://www.w3.org/1999/XSL/Transform"</span>
<span class="na">xmlns:atom=</span><span class="s">"http://www.w3.org/2005/Atom"</span>
<span class="na">exclude-result-prefixes=</span><span class="s">"atom"</span>
<span class="nt">&gt;</span>
<span class="nt">&lt;xsl:output</span> <span class="na">method=</span><span class="s">"html"</span> <span class="na">version=</span><span class="s">"1.0"</span> <span class="na">encoding=</span><span class="s">"UTF-8"</span> <span class="na">indent=</span><span class="s">"yes"</span><span class="nt">/&gt;</span>
<span class="nt">&lt;xsl:template</span> <span class="na">match=</span><span class="s">"/"</span><span class="nt">&gt;</span>
  <span class="nt">&lt;html</span> <span class="na">xmlns=</span><span class="s">"http://www.w3.org/1999/xhtml"</span><span class="nt">&gt;</span>
    {% include head.html %}
    <span class="nt">&lt;body&gt;</span>
      <span class="nt">&lt;header&gt;</span>
        <span class="nt">&lt;center</span> <span class="na">class=</span><span class="s">"home-top"</span><span class="nt">&gt;&lt;a</span> <span class="na">href=</span><span class="s">"/"</span><span class="nt">&gt;</span>
            <span class="nt">&lt;svg</span> <span class="na">width=</span><span class="s">"80"</span> <span class="na">height=</span><span class="s">"60.5"</span> <span class="na">version=</span><span class="s">"1.1"</span> <span class="na">viewBox=</span><span class="s">"0 0 80 60.5"</span> <span class="na">xmlns=</span><span class="s">"http://www.w3.org/2000/svg"</span><span class="nt">&gt;&lt;g</span> <span class="na">transform=</span><span class="s">"matrix(1.76 0 0 1.76 -2.4 -12.1)"</span><span class="nt">&gt;&lt;g</span> <span class="na">fill=</span><span class="s">"#a9b1d6"</span><span class="nt">&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m36.9 6.84-0.79 4.5 2.77-0.913z"</span><span class="nt">/&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m33.2 7.73 0.288 4.14 2.66-0.523z"</span><span class="nt">/&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m29.9 9.46 1.1 4.2 2.5-1.79z"</span><span class="nt">/&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m27.1 11.7 1.75 4.28 2.13-2.32z"</span><span class="nt">/&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m24.8 14.5 2.6 4.2 1.4-2.68z"</span><span class="nt">/&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m23.1 17.6 3.71 3.53v-3.15z"</span><span class="nt">/&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m39.9 9.33a15.3 15.4 0 0 0-15 12.5l4.42-0.877a1.88 1.88 0 0 1 1.91 0.77 9.69 9.74 0 0 1 9.18-6.69 9.69 9.74 0 0 1 6.22 2.27l-0.345-6.53a15.3 15.4 0 0 0-6.38-1.4zm-15.1 17.7a15.3 15.4 0 0 0 13.3 13l-1.24-6.24a9.69 9.74 0 0 1-5.74-6.45 1.88 1.88 0 0 1-1.79 0.617zm21.9 5.15a9.69 9.74 0 0 1-3.22 1.78l-1.18 5.96a15.3 15.4 0 0 0 4.05-1.2z"</span> <span class="na">stop-color=</span><span class="s">"#000000"</span><span class="nt">/&gt;&lt;/g&gt;&lt;g</span> <span class="na">fill=</span><span class="s">"#9ece6a"</span><span class="nt">&gt;&lt;g</span> <span class="na">stroke-linecap=</span><span class="s">"round"</span> <span class="na">stroke-linejoin=</span><span class="s">"round"</span><span class="nt">&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m30.1 23.6a0.792 0.792 0 0 0-0.792 0.792 0.792 0.792 0 0 0 0.792 0.792h7.69a0.792 0.792 0 0 0 0.792-0.792 0.792 0.792 0 0 0-0.792-0.792z"</span> <span class="na">color=</span><span class="s">"#000000"</span><span class="nt">/&gt;&lt;path</span> <span class="na">class=</span><span class="s">"a"</span> <span class="na">d=</span><span class="s">"m29.7 26.1-8.41-1.67 8.41-1.67z"</span> <span class="na">stroke=</span><span class="s">"#9ece6a"</span><span class="nt">/&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m40.2 21.2c-1.75 0-3.19 1.43-3.19 3.18s1.44 3.18 3.19 3.18 3.19-1.43 3.19-3.18-1.44-3.18-3.19-3.18zm0 1.58c0.897 0 1.61 0.706 1.61 1.59 0 0.886-0.708 1.59-1.61 1.59s-1.61-0.706-1.61-1.59c0-0.886 0.708-1.59 1.61-1.59z"</span> <span class="na">color=</span><span class="s">"#000000"</span><span class="nt">/&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m40.9 32.3a0.792 0.591 0 0 1-0.792 0.591 0.792 0.591 0 0 1-0.792-0.591v-5.74a0.792 0.591 0 0 1 0.792-0.591 0.792 0.591 0 0 1 0.792 0.591z"</span> <span class="na">color=</span><span class="s">"#000000"</span><span class="nt">/&gt;&lt;path</span> <span class="na">class=</span><span class="s">"a"</span> <span class="na">d=</span><span class="s">"m38.5 32.2 1.67 8.41 1.67-8.41z"</span> <span class="na">stroke=</span><span class="s">"#9ece6a"</span><span class="nt">/&gt;&lt;/g&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m1.36 30.2v4.89l4.93 4.89v-9.77z"</span><span class="nt">/&gt;&lt;/g&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m6.25 40h8.35v-4.89h-8.35z"</span> <span class="na">fill=</span><span class="s">"#739449"</span><span class="nt">/&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m6.35 13.6h8.2v-4.89h-8.2z"</span> <span class="na">fill=</span><span class="s">"#739449"</span><span class="nt">/&gt;&lt;g</span> <span class="na">fill=</span><span class="s">"#9ece6a"</span><span class="nt">&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m14.5 40h0.0928l4.84-4.89h-4.93z"</span><span class="nt">/&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m14.6 8.74v4.89h4.93z"</span><span class="nt">/&gt;&lt;path</span> <span class="na">d=</span><span class="s">"m14.5 13.6v21.5h4.93v-21.5h-4.89z"</span><span class="nt">/&gt;&lt;/g&gt;&lt;/g&gt;&lt;/svg&gt;</span>
        <span class="nt">&lt;/a&gt;&lt;/center&gt;</span>
        <span class="nt">&lt;center&gt;</span>
          {% include navigation.html %}
        <span class="nt">&lt;/center&gt;</span>
        <span class="nt">&lt;p&gt;</span>This is a web feed that can be viewed in the browser. <span class="nt">&lt;b&gt;</span>Subscribe for free<span class="nt">&lt;/b&gt;</span> by copying the URL <span class="nt">&lt;code&gt;</span> joelchrono.xyz/feed.xml <span class="nt">&lt;/code&gt;</span> into your RSS reader. <span class="nt">&lt;/p&gt;</span>

        <span class="nt">&lt;p&gt;</span>Read how <span class="nt">&lt;a</span> <span class="na">href=</span><span class="s">"/blog/improving-my-rss-feed/"</span><span class="nt">&gt;</span>I improved this feed, and made it <span class="nt">&lt;b&gt;</span>human-readable<span class="nt">&lt;/b&gt;&lt;/a&gt;</span>.<span class="nt">&lt;/p&gt;</span>
      <span class="nt">&lt;/header&gt;</span>
      <span class="nt">&lt;main&gt;</span>
        <span class="nt">&lt;h2&gt;&lt;svg</span> <span class="na">xmlns=</span><span class="s">"http://www.w3.org/2000/svg"</span> <span class="na">width=</span><span class="s">"24"</span> <span class="na">height=</span><span class="s">"24"</span> <span class="na">viewBox=</span><span class="s">"0 0 455.731 455.731"</span> <span class="na">xml:space=</span><span class="s">"preserve"</span><span class="nt">&gt;</span> <span class="nt">&lt;path</span> <span class="na">style=</span><span class="s">"fill:#f78422"</span> <span class="na">d=</span><span class="s">"M0 0h455.731v455.731H0z"</span><span class="nt">/&gt;</span> <span class="nt">&lt;path</span> <span class="na">style=</span><span class="s">"fill:#fff"</span> <span class="na">d=</span><span class="s">"M296.208 159.16C234.445 97.397 152.266 63.382 64.81 63.382v64.348c70.268 0 136.288 27.321 185.898 76.931 49.609 49.61 76.931 115.63 76.931 185.898h64.348c-.001-87.456-34.016-169.636-95.779-231.399z"</span><span class="nt">/&gt;</span> <span class="nt">&lt;path</span> <span class="na">style=</span><span class="s">"fill:#fff"</span> <span class="na">d=</span><span class="s">"M64.143 172.273v64.348c84.881 0 153.938 69.056 153.938 153.939h64.348c0-120.364-97.922-218.287-218.286-218.287z"</span><span class="nt">/&gt;</span> <span class="nt">&lt;circle</span> <span class="na">style=</span><span class="s">"fill:#fff"</span> <span class="na">cx=</span><span class="s">"109.833"</span> <span class="na">cy=</span><span class="s">"346.26"</span> <span class="na">r=</span><span class="s">"46.088"</span><span class="nt">/&gt;</span> <span class="nt">&lt;/svg&gt;</span> Latest 20 posts<span class="nt">&lt;/h2&gt;</span>
        <span class="nt">&lt;xsl:apply-templates</span> <span class="na">select=</span><span class="s">"atom:feed/atom:entry[position() &amp;lt;= 20]"</span><span class="nt">/&gt;</span>
      <span class="nt">&lt;/main&gt;</span>
      {% include footer.html %}
    <span class="nt">&lt;/body&gt;</span>
  <span class="nt">&lt;/html&gt;</span>
  <span class="nt">&lt;/xsl:template&gt;</span>
  <span class="nt">&lt;xsl:template</span> <span class="na">match=</span><span class="s">"atom:entry"</span><span class="nt">&gt;</span>
    <span class="nt">&lt;article</span> <span class="na">class=</span><span class="s">"posts wrapper"</span><span class="nt">&gt;</span>
      <span class="nt">&lt;p</span> <span class="na">class=</span><span class="s">"blog-data"</span><span class="nt">&gt;&lt;a</span> <span class="na">href=</span><span class="s">"{atom:link[@rel='alternate']/@href}"</span><span class="nt">&gt;&lt;b&gt;&lt;xsl:value-of</span> <span class="na">select=</span><span class="s">"atom:title"</span><span class="nt">/&gt;&lt;/b&gt;&lt;/a&gt;&lt;/p&gt;</span>
      <span class="nt">&lt;div&gt;&lt;xsl:value-of</span> <span class="na">select=</span><span class="s">"atom:summary"</span> <span class="na">disable-output-escaping=</span><span class="s">"yes"</span> <span class="nt">/&gt;&lt;/div&gt;</span>
      <span class="nt">&lt;small</span> <span class="na">class=</span><span class="s">"post-date"</span><span class="nt">&gt;</span>
        <span class="c">&lt;!--Display the date in YYYY-MM-DD format--&gt;</span>
        <span class="nt">&lt;xsl:variable</span> <span class="na">name=</span><span class="s">"year"</span> <span class="na">select=</span><span class="s">"substring(atom:published, 1, 4)"</span><span class="nt">/&gt;</span>
        <span class="nt">&lt;xsl:variable</span> <span class="na">name=</span><span class="s">"month"</span> <span class="na">select=</span><span class="s">"substring(atom:published, 6, 2)"</span><span class="nt">/&gt;</span>
        <span class="nt">&lt;xsl:variable</span> <span class="na">name=</span><span class="s">"day"</span> <span class="na">select=</span><span class="s">"substring(atom:published, 9, 2)"</span><span class="nt">/&gt;</span>
        <span class="nt">&lt;xsl:value-of</span> <span class="na">select=</span><span class="s">"concat($year, '-', $month, '-', $day)"</span><span class="nt">/&gt;</span>
      <span class="nt">&lt;/small&gt;</span>
    <span class="nt">&lt;/article&gt;</span>
  <span class="nt">&lt;/xsl:template&gt;</span>
<span class="nt">&lt;/xsl:stylesheet&gt;</span>
</code></pre></div></div>

<p>You can check out how my RSS feed like in any browser! You will probably not be able to tell it is an xml file, but when you paste it into your RSS feed reader, it will be recognized like any other!</p>

<h1 id="final-thoughts">Final thoughts</h1>

<p>The new features in my RSS feed are honestly quite simple, and seem pretty easy to achieve now that I put my mind into it. I wonder why didn’t I do this sooner. Now I have to go back and edit the last line of every single markdown file in my posts folder, containing the include I no longer need…</p>

<p>Or I can write a script, and then blog about that :P</p>

<p>This is day 14 of <a href="https://100daystooffload.com">#100DaysToOffload</a></p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="blog" /><category term="jekyll" /><category term="coding" /><category term="rss" /><summary type="html"><![CDATA[I did some changes to my website once again, and I changed the way my RSS feed works!]]></summary></entry><entry><title type="html">Inbox Zero But RSS</title><link href="https://joelchrono.xyz/blog/inbox-zero-but-rss/" rel="alternate" type="text/html" title="Inbox Zero But RSS" /><published>2024-02-09T17:07:03-06:00</published><updated>2024-02-09T17:07:03-06:00</updated><id>https://joelchrono.xyz/blog/inbox-zero-but-rss</id><content type="html" xml:base="https://joelchrono.xyz/blog/inbox-zero-but-rss/"><![CDATA[<p>So <a href="https://fosstodon.org/@joel/111886169699083768">last Tuesday I commited an atrocity</a>, that annoyed me to no end, at least for an hour or so until I thought about it.</p>

<p>If you didn’t open that link, that’s quite sad, but basically I marked all of the feeds in my FreshRSS instance as read, something that was done by accident and would get rid of my backlog of blogposts I would have liked to read at some point.</p>

<p>I mean, the articles are still there and my purging policy is really forgiving, but I have no way to tell what I already read from what I had not.</p>

<p>Regardless, this ended up being a bit of a blank slate now, thankfully, <a href="https://matthewgraybosch.com/">Matthew Graybosch</a> had this fantastic comment!</p>

<blockquote>
  <p>More articles will come. Just give it time. Or add more feeds.</p>

  <p>— <a href="https://libranet.de/display/0b6b25a8-1865-c287-98d3-292430198077">Matthew Graybosch</a></p>
</blockquote>

<p>So, I decided to add more RSS feeds! And it was great!</p>

<h1 id="but-where-did-you-find-those">But where did you find those?</h1>

<p>Blogs! Of course, I barely read news on my RSS feed actually, so I decided to checkout the blogrolls of the websites I already follow, I ended up finding quite a few gems that way. An even quicker way to find random blogs to add to my RSS reader was making use of <a href="blogroll.org/ze-randomizer">Ye Olde Blogroll’s Randomizer</a>, which worked wonderfully too!</p>

<p>Some of the blogs I found that you might like are the following!</p>

<ul>
  <li><a href="https://analogoffice.net/">Analog Office</a>: This blog has a bunch of articles about analog stuff, paper planners, handwriting and the like. Very nice stuff.</li>
  <li><a href="https://colinwalker.blog/">Colin Walker</a>: This blog is pretty much just a journal filled with everything. Just a blog about blogging, writing and tinkering in general, Colin seems like a nice guy!</li>
  <li><a href="https:/controllingthetransmissions.blogspot.com/">Controlling the Transmissions</a>: This website has many book reviews from some guy who just read Childhood’s End <a href="/blog/childhoods-end-review/">like me!</a></li>
  <li><a href="https://cyb.org.uk/">cyb.org.uk</a>: Its always nice to find more blogs just talking about the way they do things I already do, technology and open source in general.</li>
  <li><a href="https://sive.rs/en.atom">Derek Sivers blog</a>: This is the guy who inspired me to do my <a href="/now">/now</a> page so, while he doesn’t blog as much I added him anyway.</li>
  <li><a href="https://fluxtaposed.com/">Hey Fluxay!</a>: Its Fluxay! I don’t know, he’s fun! Recently released the last episode of his podcast (so far), and may blog more later.</li>
  <li><a href="https://lastcontact.space/">Last Contact</a>: This is a bit of a sci-fi story, published over time! It’s quite good!</li>
  <li><a href="https://marcthiele.com/">Marc Thiele’s Journal</a>: This one just showed up in the Blogroll randomizer and I’ve only read a couple of articles, good stuff though!</li>
  <li><a href="https://musingsfromatangledmind.com/">Musings from a Tangled Mind</a>: The musings from a tangled mind, from an anonymous author, talking about whatever happens in their life.</li>
  <li><a href="https://rebeccatoh.co/">rebeccatoh.co</a>: Just another personal website that I found randomly too!</li>
  <li><a href="https://robinrendle.com/">Robin Rendle</a>: This one was from <a href="https://kevquirk.com/blogroll">Kev Quirk’s blogroll!</a>, the RSS feed here is actually complete, so I have 800 or so unread articles now in one fell swoop!</li>
  <li><a href="https://thekjd.net/">The Knee Jerk Devotional</a>: Daily posts about faith, the bible and stuff like that, I think its pretty good.</li>
</ul>

<h1 id="changing-my-rss-reading-habits">Changing my RSS reading habits</h1>

<p>Because I marked everything as read, and I also removed a bunch of the spammy news feeds. I will get a lot less, but hopefully more meaningful content coming up. I decided to limit the few big sources I still have to mark as read older articles (or whenever up to 20 are still unread). I also added a lot of word filters for more stuff I don’t care about, words like “Amazon”, “Subscription” and whatever else. Much better.</p>

<p>Because of the amount of feeds I removed, as well as the list of feeds I added, I think I’ll need to reorganize my categories at some point too, since right now the biggest ones are “100DaysToOffload” for people doing the challenge and “Personal Websites” for literally everyone else. While the rest of news, updates and comics are only a small fraction in comparison. There’s always work to do I guess.</p>

<p>Regardless, now  I should be able to just read whatever and have a good list of articles to check out when I have the time at a constant rate. <a href="/blog/so-many-feeds-to-follow/">I kind of wrote about that before</a> but it didn’t stick for me, because of my huge backlog—which no longer exists. As long as I manage to catch up with Robin Rendle’s archive…</p>

<p>This is day 10 of <a href="https://100daystooffload.com">#100DaysToOffload</a>!</p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="rss" /><category term="blog" /><category term="reading" /><category term="internet" /><summary type="html"><![CDATA[So, I accidentally marked as read every single feed in my FreshRSS instance, but I decided to make the best of it!]]></summary></entry><entry><title type="html">Word filters are great</title><link href="https://joelchrono.xyz/blog/word-filters/" rel="alternate" type="text/html" title="Word filters are great" /><published>2023-10-10T12:30:00-06:00</published><updated>2023-10-10T12:30:00-06:00</updated><id>https://joelchrono.xyz/blog/word-filters</id><content type="html" xml:base="https://joelchrono.xyz/blog/word-filters/"><![CDATA[<p>With the quantity of information we expose ourselves to everyday, I think word filters are a great idea, be it on your feed reader or social media of choice, they’re pretty useful!</p>

<p>The world’s is upside down lately, and there are a lot of things I would rather avoid, and I am sure I’m not the only one with this problem.</p>

<p>Of course, I am talking about Amazon’s Prime Day deals, I don’t like Prime Day deals, they’re coarse and rough and irritating… and they get everywhere. Not like here. Here everything is soft and smooth, and full of nice geeky references.</p>

<p>Thankfully, FreshRSS, <a href="/blog/self-hosting-my-news-feed-with-freshrss">which I’ve been using for a while</a>, allows me to automatically set as read any article in a manner of ways. For example, based on the title of the article, it’s author, or the content of it! All you need to do this is go to the feed settings of whatever website you want to configure, scroll down to the <strong>Filter Actions</strong> section, and set whatever parameters you want using a format like this example:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>intitle:"prime day"
author:"kev quirk"
inurl:"amazon"
</code></pre></div></div>

<p>You can check <a href="https://freshrss.github.io/FreshRSS/en/users/10_filter.html">FreshRSS’s documentation</a> for more options to try out!</p>

<p>Of course, Mastodon also has a great word filter feature, which will automatically hide posts in your timeline if they use a word you have blocked. You can even choose to just minimize the post with the possibility of expanding it, or just hide it completely, never to be seen again.</p>

<p>Overall, Mastodon users are quite alright at using content warnings and moderating themselves, but a few things are bound to slip and if you know you dislike reading about certain things, you should do your homework too!</p>

<p>Simply go to <em>Mastodon’s settings &gt; Filters &gt; Add new filter</em> and filter away!</p>

<p>This is post 71 of <a href="https://100daystooffload.com">#100DaysToOffload</a>. Have a good rest of your day, fellow reader. 😊</p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="rss" /><category term="internet" /><category term="thoughts" /><summary type="html"><![CDATA[Word filters are a pretty useful feature to have, both on your feed reader and your social media of choice.]]></summary></entry><entry><title type="html">FreshRSS and Nextcloud broke</title><link href="https://joelchrono.xyz/blog/freshrss-and-nextcloud-broke/" rel="alternate" type="text/html" title="FreshRSS and Nextcloud broke" /><published>2023-01-31T14:00:00-06:00</published><updated>2023-01-31T14:00:00-06:00</updated><id>https://joelchrono.xyz/blog/breaking-my-selhosted-services</id><content type="html" xml:base="https://joelchrono.xyz/blog/freshrss-and-nextcloud-broke/"><![CDATA[<p>As my rabbithole on RSS kept going down. I eventually decided to go and import even more feeds to my FreshRSS instance, because sometimes you just feel like the web is terrible and decide run away from it as much as you can, util it is too much of a hassle and the balance returns.</p>

<h1 id="how-i-broke-freshrss">How I broke FreshRSS</h1>

<p>So, I decided to import my Youtube subscriptions, the way I did it was kinda neat. I had found this javascript bookmark that may be better for you, since its <em>just a bit</em> faster than using Google Takeout just for subscriptions.</p>

<div class="language-javascript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nx">javascript</span><span class="p">:</span><span class="k">if</span><span class="p">(</span><span class="dl">"</span><span class="s2">https://www.youtube.com/feed/channels</span><span class="dl">"</span><span class="o">==</span><span class="nb">window</span><span class="p">.</span><span class="nx">location</span><span class="p">.</span><span class="nx">href</span><span class="p">){</span><span class="kd">let</span> <span class="nx">e</span><span class="o">=</span><span class="p">[...</span><span class="nb">document</span><span class="p">.</span><span class="nf">querySelectorAll</span><span class="p">(</span><span class="dl">"</span><span class="s2">#main-link.channel-link</span><span class="dl">"</span><span class="p">)].</span><span class="nf">map</span><span class="p">(</span><span class="nx">e</span><span class="o">=&gt;</span><span class="p">{</span><span class="kd">const</span><span class="p">[,</span><span class="nx">t</span><span class="p">,</span><span class="nx">n</span><span class="p">]</span><span class="o">=</span><span class="nx">e</span><span class="p">.</span><span class="nx">href</span><span class="p">.</span><span class="nf">match</span><span class="p">(</span><span class="dl">"</span><span class="s2">/((?:user)|(?:channel))/(.*)$</span><span class="dl">"</span><span class="p">);</span><span class="k">return</span><span class="dl">"</span><span class="s2">https://www.youtube.com/feeds/videos.xml?</span><span class="dl">"</span><span class="o">+</span><span class="p">(</span><span class="dl">"</span><span class="s2">user</span><span class="dl">"</span><span class="o">===</span><span class="nx">t</span><span class="p">?</span><span class="dl">"</span><span class="s2">user=</span><span class="dl">"</span><span class="p">:</span><span class="dl">"</span><span class="s2">channel_id=</span><span class="dl">"</span><span class="p">)</span><span class="o">+</span><span class="nx">n</span><span class="p">}).</span><span class="nf">join</span><span class="p">(</span><span class="dl">"</span><span class="se">\n</span><span class="dl">"</span><span class="p">);</span><span class="nx">e</span><span class="p">?</span><span class="nb">navigator</span><span class="p">.</span><span class="nx">clipboard</span><span class="p">.</span><span class="nf">writeText</span><span class="p">(</span><span class="nx">e</span><span class="p">).</span><span class="nf">then</span><span class="p">(()</span><span class="o">=&gt;</span><span class="nf">alert</span><span class="p">(</span><span class="dl">"</span><span class="s2">A%20list%20of%20channel%20RSS%20feeds%20has%20been%20copied%20to%20the%20clipboard.%20</span><span class="se">\n</span><span class="s2">Paste%20these%20into%20rssmix.com%20to%20generate%20a%20single%20RSS%20feed,%20or%20opml-gen.ovh%20to%20generate%20an%20OPML%20file.</span><span class="dl">"</span><span class="p">)).</span><span class="k">catch</span><span class="p">(()</span><span class="o">=&gt;</span><span class="p">{</span><span class="nx">console</span><span class="p">.</span><span class="nf">log</span><span class="p">(</span><span class="nx">e</span><span class="p">),</span><span class="nf">alert</span><span class="p">(</span><span class="dl">"</span><span class="s2">A%20list%20of%20channel%20RSS%20feeds%20has%20logged%20to%20the%20console.%20(Unable%20to%20copy%20to%20clipboard)%20</span><span class="se">\n</span><span class="s2">Paste%20these%20into%20rssmix.com%20to%20generate%20a%20single%20RSS%20feed,%20or%20opml-gen.ovh%20to%20generate%20an%20OPML%20file.</span><span class="dl">"</span><span class="p">)}):</span><span class="nf">alert</span><span class="p">(</span><span class="dl">"</span><span class="s2">Couldn't%20find%20any%20subscriptions</span><span class="dl">"</span><span class="p">)}</span><span class="k">else</span><span class="o">%</span><span class="mi">20</span><span class="nf">alert</span><span class="p">(</span><span class="dl">'</span><span class="s1">Please%20run%20at%20"https://www.youtube.com/feed/channels"</span><span class="dl">'</span><span class="p">);</span>
</code></pre></div></div>

<p>All you need to do to make it work is go <a href="https://www.youtube.com/feed/channels">here</a>, scroll ALL the way to the bottom, it might take a while, so use the EndPage key or something a couple of times, or a dozen if you are susbribed to many channels like me. Once done, just run the bookmarklet and all the feed urls will be copied to your clipboard. After that, I found an <a href="https://opml-gen.ovh/">online OPML generator</a>, but you can probably use some bash script too, this time I was lazy.</p>

<p>After that I imported the OPML file to FreshRSS and that’s where the fun begun.</p>

<p>For some reason, I thought that adding 1200 feeds at once would be a decent idea, it was not. The import process took a while, a long while. Even if it didn’t actually break, it was a pain to use and doing a refresh was painfully bad.</p>

<h2 id="bulk-deletion-of-feed-subscriptions">Bulk deletion of feed subscriptions</h2>

<p>I decided to try and remove them. Sadly, as of now there is no way to delete subscriptions in bulk. So I had to fiddle around with the MySQL database via SSH.</p>

<p>Of course, <strong>before doing all this backing up the database is a good idea</strong>. But I didn’t think anything too bad could happen, don’t follow my example though.</p>

<p>I ran the following command, after getting into the freshrss database:</p>

<div class="language-sql highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">DELETE</span> <span class="k">FROM</span> <span class="n">freshrss_</span><span class="err">$</span><span class="n">user_feed</span> <span class="k">WHERE</span> <span class="n">category</span> <span class="o">=</span> <span class="mi">14</span><span class="p">;</span> <span class="c1">-- user is your username</span>
</code></pre></div></div>

<p>Of course, to get the category and table name, you should use commands such as <code class="language-plaintext highlighter-rouge">show tables;</code> and also checking the category number in the <code class="language-plaintext highlighter-rouge">freshrss_$user_category</code> with <code class="language-plaintext highlighter-rouge">SELECT * FROM freshrss_$user_category;</code>. But while I am kinda used to MySQL, not everyone is, I hope bulk actions become a thing soon enough in FreshRSS.</p>

<h1 id="and-now-nextcloud-too-️">And now Nextcloud too… 🤦🏻‍♂️</h1>

<p>Later I also decided to check my Yunohost admin settings and saw that some of my applications had updates available. Nextcloud is always down for a while when its being updated, so that’s all right.</p>

<p>I was able to login to Nextcloud just fine from the browser, and verify it updated correctly.</p>

<p>However, I noticed that my desktop client couldn’t connect, and also DAVx5 stopped working, no luck with vdirsyncer. No matter how many times I tried to authenticate, generating an app password would fail as fail.</p>

<p>I actually did quite a bit of things trying to fix this. I changed my domain name, changed the certificates, compared with the example nginx configuration in Nextcloud’s documentation, even a full reboot, nothing worked.</p>

<p>Thankfully, after a while asking around in the Yunohost IRC chat, I discovered <a href="https://forum.yunohost.org/t/authentication-issues-with-yunohost-11-1-0-with-new-ssowat-version-please-upgrade-to-yunohost-11-1-2-to-fix/23059">this thread</a> that had a pinned solution, which worked perfectly fine for me.</p>

<p>Turns out I am using a testing release of Yunohost that got accidentally tagged as stable, and the best course of action at the moment is going all out and switching to the testing branch, at least until a real stable version comes out. I decided to do the change and after the update process completed, Nextcloud worked fine again. Basically, I just ran this on my terminal:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl https://install.yunohost.org/switchtoTesting | bash
</code></pre></div></div>

<p>I am glad this problem got solved so easily and I didn’t need to move or edit too many files, because I would have never figured this out myself.</p>

<h1 id="final-thoughts">Final thoughts</h1>

<p>Well, at least I changed the domain for a better one, since I was using one of those free domains Nextcloud can give you. For now its all fine.</p>

<p>I also decided to import my subscriptions from Newpipe instead, since I follow less channels, that end up being more meaningul for me than those hundreds of old channels I had in my YouTube subscriptions.</p>

<p>Sadly, Newpipe has no way to export to OPML. So once again I went and parsed their json file using sed and formatted it properly using the tool I mentioned before.</p>

<p>Everything is running as expected now.</p>

<p>I actually made blogs daily blogs for thw whole of January, this is actually quite incredible for me, I think I will take a bit of a break, but maybe not. It depends on how I feel.</p>

<p>This is day 31 of <a href="https://100daystooffload.com">#100DaysToOffload</a></p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="selfhost" /><category term="raspberrypi" /><category term="rss" /><category term="tutorial" /><summary type="html"><![CDATA[You gotta love when you decide you want to do something completely non-sensical. Its even better if you actually get away with it, mostly without any losses. Its not as funny when the software itself decides to do the non-sensical things though. Here's how I fixed it all.]]></summary></entry><entry><title type="html">Newsboat queries and FreshRSS web scraping</title><link href="https://joelchrono.xyz/blog/newsboat-queries-and-freshrss-scraping/" rel="alternate" type="text/html" title="Newsboat queries and FreshRSS web scraping" /><published>2023-01-30T15:50:00-06:00</published><updated>2023-01-30T15:50:00-06:00</updated><id>https://joelchrono.xyz/blog/newsboat-is-even-better-with-queries</id><content type="html" xml:base="https://joelchrono.xyz/blog/newsboat-queries-and-freshrss-scraping/"><![CDATA[<p>So after a rabbit hole checking out some channel recommendations by The Linux Cast’s <a href="https://youtu.be/BoFvhB9krEo">latest video</a>. I stumbled upon some videos and content related to RSS that ended up making me do this blogpost sharing what I learned. I will mention the sources as I go.</p>

<h1 id="newsboat-queries-are-what-i-need">Newsboat queries are what I need</h1>

<p>All this time, I’ve actually been using FreshRSS’ web UI more often than Newsboat. The reason?</p>

<p>FreshRSS shows me all the posts from all the sources that belong to a category, letting me filter out what I wanted. Newsboat, by default, will start up showing all the sources, and then you would be able to open them one by one, and individually check their feeds. It has a way to see all the tags (which would be categories on FreshRSS), but opening one would, again only open the sources, where I would only be able to navigate one feed at a time.</p>

<p>The thing is, I mostly follow personal blogs, and even if the people I follow were like me and did one post per day, being able to just read their feed would mean that I would only have a couple posts until I stumbled upon an article I already read. I wanted to have all the posts from everyone I followed! I just didn’t know if it was possible…</p>

<p>However, today I learned about <a href="https://newsboat.org/releases/2.30.1/docs/newsboat.html#_query_feeds">Newsboat queries</a>, and its an absolute game changer for me. Using a relatively simple syntax, I can create my own feeds, which are populated by whatever fits a query I can define. This is achieved by adding something like the following to my urls file:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>"query:Personal Sites:tags =~ \"Personal sites\"" "Personal sites"
"query:Company Blogs:tags =~ \"Company Blogs\"" "Company Blogs"
</code></pre></div></div>

<p>You can even use some other parameters to make more specific queries, like filtering based on the article title contents:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>"query:1080p Torrents:tags =~ \"Torrents\" and (title =~ \"1080\" ) ""Torrents"
</code></pre></div></div>

<p>The official documentation I linked has some more examples. And a <a href="https://youtu.be/PUxPUdyCy_U">here’s a video</a> by <a href="https://www.youtube.com/@gotbletu">@gotbletu</a> that explains it a bit more. I had actually already watched one of his other videos <a href="https://www.youtube.com/watch?v=RWk8OIi82U4">about using FreshRSS with Newsboat and mobile apps</a>, but I somehow missed that he was using queries. They are truly awesome.</p>

<h1 id="using-freshrss-for-web-scraping">Using FreshRSS for web scraping</h1>

<p>There are a ton of websites out there, however, not all of them are the same, and not all of them are kind enough to provide an RSS feed. With the release of FreshRSS 1.20, scraping websites using XPath became possible. However I had been lazy and ignorant on what it did, so I didn’t bother trying it out. After all, there are a lot of websites that already have RSS, and if one refused, I am sure there would be others I could use instead.</p>

<p>But I decided to give the feature a try after finding <a href="https://danq.me/2022/09/27/freshrss-xpath/">a blogpost on how to do it</a>, which was cited by gotbletu. Just like in that article, I will use a website as an example. Lets go for <a href="https://www.casio.com/intl/news/">Casio’s news section</a>, because I quite like Casio watches.</p>

<h2 id="steps-to-follow">Steps to follow</h2>

<ol>
  <li><strong>Add a url:</strong> the plain url, since there’s no feed.</li>
  <li><strong>Add a Feed title:</strong> this can be obtained with a query (usually something like <code class="language-plaintext highlighter-rouge">//title</code> or in this case, <code class="language-plaintext highlighter-rouge">//h1</code>) or set as a string.</li>
  <li><strong>Set what defines an item:</strong> using your browser’s developer tools, you can use the inspector to check the html and find if there’s a class or something that defines an article. In this case, something like:
    <div class="language-html highlighter-rouge"><div class="highlight"><pre class="highlight"><code>//a[@class="cmp-newslist__link"]
</code></pre></div>    </div>
  </li>
  <li><strong>Item title:</strong> this should be relative to the item. In Casio’s case its something like:
    <div class="language-html highlighter-rouge"><div class="highlight"><pre class="highlight"><code>descendant::div[@class="cmp-newslist-item__title"]
</code></pre></div>    </div>
  </li>
  <li><strong>Item link:</strong> This maybe a tricky one, but not really, since the link is already in the main item, in this case we do:
    <div class="language-html highlighter-rouge"><div class="highlight"><pre class="highlight"><code>@href
</code></pre></div>    </div>
  </li>
  <li><strong>Item content:</strong> Sometimes there is a summary or description, this is not the case here. But its similar to the item title.</li>
  <li><strong>Item date:</strong> From here on, its all up to what you can parse, and how well structured the website is. For the date here I had:
    <div class="language-html highlighter-rouge"><div class="highlight"><pre class="highlight"><code>descendant::div[@class="cmp-newslist-item__date"]
</code></pre></div>    </div>
  </li>
</ol>

<p>Other things such as author, thumbnails and so on can be extrapolated quite easily, or see the blogpost if you need more help. To finish, just hit the <strong>Add</strong> button and test things out!</p>

<p>Sometimes, like me, you will not fetch the things you intended to. You may have problems and its a matter of experience, trial and error and getting used to how HTML and the XPath syntax work. Some of the problems that may happen are getting the wrong date, having the item link go to the main website instead, or no items showing up at all. Keep trying!</p>

<h2 id="full-article-content">Full article content?</h2>

<p>Of course, XPath works to fetch the items and basic metadata from whatever list, feed or archive is used by the website you are scraping. In case you want to learn how to get the full article content too, using FreshRSS’s CSS selector feature, <a href="https://joelchrono.xyz/blog/fetch-full-article-content-freshrss/">I wrote a tutorial for that too</a>. Since then, a couple extra features, such as ignoring some sections of the contents has been added. So please explore the features of FreshRSS, its fun. Feel free to check <a href="https://joelchrono.xyz/tags/rss">other posts I did related to RSS</a></p>

<figure class="img">
  <picture>
    <source srcset="/assets/img/blogs/2023-01-30-newsboat-freshrss.webp" type="image/webp" />
    <source srcset="/assets/img/blogs/2023-01-30-newsboat-freshrss.png" type="image/png" />
    <img class="mx-auto" src="/assets/img/blogs/2023-01-30-newsboat-freshrss.png" alt="Newsboat query feed and the inspector view of the Casio website" />
  </picture>
  <figcaption class="caption">Newsboat query feed and the inspector view of the Casio website in a sick thumnail I edited with GIMP</figcaption></figure>

<p>This one actually feels like a rather nice blog instead of my typical bursts of kinda whatever content I write in a whim. I did put some effort into this one (its actually more than a thousand words 🤯), so I hope you enjoyed it, just like I enjoyed improving my RSS experience and writing this down.</p>

<p>I love RSS, I love FreshRSS, I love Newsboat, and I love you, dear reader!</p>

<p>This is day 30 of <a href="https://100daystooffload.com">#100DaysToOffload</a></p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="linux" /><category term="foss" /><category term="rss" /><summary type="html"><![CDATA[I have talked about RSS a lot, my favorite client on my desktop is Newsboat, and queries are a feature I did not know existed until now, and I can not believe how I lived without them. Likewise, FreshRSS got a great feature a while ago, that allows me to scrape websites using XPath, and its awesome!]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://joelchrono.xyz/assets/img/blogs/2023-01-30-newsboat-freshrss.png" /><media:content medium="image" url="https://joelchrono.xyz/assets/img/blogs/2023-01-30-newsboat-freshrss.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">So many feeds to follow</title><link href="https://joelchrono.xyz/blog/so-many-feeds-to-follow/" rel="alternate" type="text/html" title="So many feeds to follow" /><published>2023-01-27T10:03:16-06:00</published><updated>2023-01-27T10:03:16-06:00</updated><id>https://joelchrono.xyz/blog/the-blogging-world-is-huge</id><content type="html" xml:base="https://joelchrono.xyz/blog/so-many-feeds-to-follow/"><![CDATA[<p>Ever since I started using RSS feeds, I’ve been expanding my list of feeds multiple times. I’ve also started over and over, because I didn’t take care of my backups as much.</p>

<p>Anyway, it was not until two years ago, that most of my feeds were those of common tech news sites and even some YouTube channels. Back then I didn’t care much about blogging or what other people had to say, unless they were in video format, I guess.</p>

<p>Clearly all of that changed once I joined Fosstodon and discovered the blogging sphere. I’ve joined a <a href="https://fediring.net/">webrings</a>, some <a href="https://512kb.club/">clubs</a>, and other nerdy things like that, because why not.</p>

<p>Lately, I’ve added a ton of new blogs to my feed, and I came across an article by <a href="https://social.rachsmith.com/@rach">Rach Smith</a> about the <a href="https://rachsmith.com/subscribe-a-lot-consume-a-little/">way she consumes content online</a>. Basically, subscribe to everything and pick what to check and utterly ignore the rest.</p>

<p>I’ve been doing pretty much the same thing, except that my current clients don’t make it as easy, or so I thought.</p>

<p>Swiping to either ignore or queue up is actually kind of a cool feature that both of my mobile clients for podcasts and web feeds can do.</p>

<p><a href="https://antennapod.org/">AntennaPod</a>, my podcast app of choice, recently added a new Inbox screen. Which is pretty much a general feed with new episodes of all podcasts (I can also whitelist them, I believe) and just by swiping left or right, I can ignore them or add them to my queue of episodes to listen to. This is not the best for some types of podcasts, but for the news and weekly content I follow, is actually awesome.</p>

<p><a href="https://github.com/readrops/Readrops">Readrops</a>, my RSS reader of choice on Android, has a To Read section, and its also a matter of swiping left or right, to hide an article (although I can also show read articles if I want to) or to add it to my reading list.</p>

<p>This is quite great, because I can now parse all feeds and categories and quickly get a general stream of articles I am actually interested on reading later. If only it didn’t have an outdated design…</p>

<p><a href="https://github.com/Ashinch/ReadYou">Read You</a>, a reader I’ve been watching grow and improve may become my new choice once FreshRSS support works properly. Right now they added Fever API support, but its still a bit rough around the edges.</p>

<p>Regardless, I think I found a better way to consume this content. So I am glad I came across that article, now its just a matter of sticking with it.</p>

<p>On desktop I don’t really mind having to still deal with the usual interface, since FreshRSS also has a mark as read button, even if it doesn’t hide the post immediately, I don’t mind it much. My eyes already ignore them anyways.</p>

<p>In the span of me starting this blog and me finishing it, I already added 4 new feeds I just discovered to my FreshRSS instance. So there’s that.</p>

<p>This is day 27 of <a href="https://100daystooffload.com">#100DaysToOffload</a></p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="internet" /><category term="blog" /><category term="lifestyle" /><category term="rss" /><summary type="html"><![CDATA[I love blogs, I love digital gardens. Since I started this journey I keep finding site after site and I recently added so many new ones to my feed, I decided to write about it.]]></summary></entry><entry><title type="html">FreshRSS Android Apps</title><link href="https://joelchrono.xyz/blog/freshrss-android-apps/" rel="alternate" type="text/html" title="FreshRSS Android Apps" /><published>2022-05-05T09:58:51-05:00</published><updated>2022-05-05T09:58:51-05:00</updated><id>https://joelchrono.xyz/blog/freshrss-android-apps</id><content type="html" xml:base="https://joelchrono.xyz/blog/freshrss-android-apps/"><![CDATA[<p>This post won’t be long, I just wanted to keep going a bit about the state of RSS reader apps on Android. Ever since <a href="https://github.com/FredJul/Flym">Flym</a> died, I have been looking for an alternative, and since I moved to FreshRSS, my needs got a bit more specific, since I need a client with support for Fever’s or Google Reader’s API. So far, nothing has managed to convinced me.</p>

<p>Locally there are many options. Feeder is probably the best we got among the FOSS apps available on F-Droid. It has been going through a UI revamp and its looking pretty good, but it has no way to sync to any APIs, only locally. The developer seems willing to accept a PR that adds this, but so far, no luck. The <a href="https://gitlab.com/spacecowboy/Feeder/-/issues/52">issue related to this</a> has been open for 4 years.</p>

<p>Apps that can sync with FreshRSS are few and far between. A quick search on F-Droid for “FreshRSS” only shows 3 results, all of them are pretty outdated. There is plain FreshRSS, which looks pretty ugly and is sluggish on my device. There is EasyRSS which looks straight out of Android KitKat. But I have to admit, it’s buttery smooth, and super lightweight too.</p>

<p>Right now, <a href="https://github.com/readrops/Readrops">Readrops</a> is the most modern looking of the bunch, and my current choice at the moment, however, it still feels a bit old. And the compatibility is bare, favorites work, but labels don’t, for example. Also, the dark theme is not of my liking.</p>

<p>There is actually another app with a very elegant design, that shows up when looking for “Fresh RSS” on F-Droid: <a href="https://github.com/yang991178/fluent-reader-lite">Fluent Reader</a>.
However, such design is following Apple’s guidelines, instead of Material design, which makes it not fit at all with the rest of my system. That’s pretty much my only complain.</p>

<p>Sadly, the current best Android client for FreshRSS is <a href="https://play.google.com/store/apps/details?id=com.seazon.feedme">FeedMe</a>, it is not FOSS, but it has support for a lot of APIs and pretty much all of the features FreshRSS comes with, its design is great and functional. The only thing I don’t like is the settings page having a sidebar, but that’s about it.</p>

<p>I am a bit conflicted between a great but proprietary product, or a decent FOSS option that mostly works for my needs. My FOSS enthusiast side ended up winning, so I have been stuck between the mobile Web UI and Readrops for a while now.</p>

<p>However, the future is a bright one, I recently stumbled upon a new kid on the block that came out on F-Droid recently. <a href="https://github.com/Ashinch/ReadYou">ReadYou</a> has a modern and beautiful UI (unless you don’t like Material You), as well as an awesome list of upcoming features, including support for the APIs supported by FreshRSS, which is exactly what I am looking for.</p>

<p>ReadYou is still implementing some basic features, so FreshRSS and sync support is still not being implemented, but the fact that its planned at all has given me hope. I decided to wait on it for now. However, it works locally just fine, so if you want to give it a go, I encourage you to try it out!</p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="rss" /><category term="ramble" /><category term="android" /><category term="opinion" /><summary type="html"><![CDATA[There are a few great RSS apps for Android, and there are even less RSS apps that support FreshRSS, but I still have hope.]]></summary></entry><entry><title type="html">Creating my own theme for FreshRSS</title><link href="https://joelchrono.xyz/blog/creating-my-own-theme-for-freshrss/" rel="alternate" type="text/html" title="Creating my own theme for FreshRSS" /><published>2022-01-12T11:11:41-06:00</published><updated>2022-01-12T11:11:41-06:00</updated><id>https://joelchrono.xyz/blog/creating-my-own-theme-for-freshrss</id><content type="html" xml:base="https://joelchrono.xyz/blog/creating-my-own-theme-for-freshrss/"><![CDATA[<p>This is going to be a simple post, because most of the effort I would put into writing something already went into editing some CSS files, therefore I’ll write something quick explaining how it went.</p>

<p>As I said before, none of the dark themes included with FreshRSS were of my liking, they were a bit too warm, almost sepia, and, as a fan of Nord’s color scheme, I wanted something colder and more blue-ish. I decided I would try and make my own theme, using a similar base to my blog’s CSS.</p>

<p>Due to how FreshRSS works, I couldn’t just slap my CSS file in there, I had to go and edit some classes and id’s from the HTML elements that looked wrong, overlapped each other or I just felt like changing a bit.</p>

<p>I also had to go ahead and edit the icons, which were a but of vector based files, I just changed the fill property according to my needs.</p>

<p>There is still a lot of work that needs to be put into this, but I think the desktop version is already quite good, and there are only some simple glitches that I could not figure out, maybe it will need some refactoring, but I guess I’ll just open source it and let somebody who wishes to put more effort into it help me.</p>

<p>You can find the repository <a href="https://github.com/joelchrono12/freshrss-nord-theme">here</a> if you wish to install it yourself or help out too!</p>

<p>If you don’t have GitHub or don’t want to use it, feel free to use <code class="language-plaintext highlighter-rouge">git send-email</code> too, I don’t mind. You can see my theme in action here:</p>

<figure class="img">
  <picture>
    <source srcset="/assets/img/blogs/2022-01-12-freshrss-nord-theme.webp" type="image/webp" />
    <source srcset="/assets/img/blogs/2022-01-12-freshrss-nord-theme.jpg" type="image/jpeg" />
    <img class="mx-auto" src="/assets/img/blogs/2022-01-12-freshrss-nord-theme.jpg" alt="" />
  </picture>
  </figure>

<p>If you want to know how to apply it here is a quick guide:</p>

<ul>
  <li>Go to your public <code class="language-plaintext highlighter-rouge">p/</code> folder</li>
  <li>cd into <code class="language-plaintext highlighter-rouge">themes/</code></li>
  <li>git clone my repository</li>
  <li>Go to FreshRSS’ display settings</li>
  <li>Select my theme and apply it</li>
</ul>

<p>This has been day 81 of <a href="https://100daystooffload.com">#100DaysToOffload</a></p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="rss" /><category term="design" /><category term="personal" /><summary type="html"><![CDATA[So the default dark themes in FreshRSS did not convince me, so I decided to create my own.]]></summary></entry><entry><title type="html">Fetch full article content in FreshRSS</title><link href="https://joelchrono.xyz/blog/fetch-full-article-content-freshrss/" rel="alternate" type="text/html" title="Fetch full article content in FreshRSS" /><published>2022-01-10T14:20:57-06:00</published><updated>2022-01-10T14:20:57-06:00</updated><id>https://joelchrono.xyz/blog/fetch-full-article-content-freshrss</id><content type="html" xml:base="https://joelchrono.xyz/blog/fetch-full-article-content-freshrss/"><![CDATA[<p>I won’t bring up any names, wait, maybe I will,
<a href="https://fosstodon.org/@ssafar">@ssafar</a>, why do you make me do this? Do you
find joy in my suffering? This blog is made because of you! I got no time to
load your WebGL rotating cube every time I open your website, fetch everything
please, I beg you, but if you don’t, no need to worry anymore!</p>

<p>Anyways, this is a tutorial made because one of the small caveats with FreshRSS
is the lack of an automatic way to fetch the full content of an article. Sites
like <a href="https://androidpolice.com">Android Police</a>, or of course, <a href="https://simonsafar.com">Simon’s
blog</a> do not give you that, sometimes because they want you to open their
site and show ads, others just because they write pure HTML instead of being
lazy (in the right ways) and let the machine generate stuff for them.</p>

<p>So, why does FreshRSS not come with this option by default? No idea, but it
does have a way to do it, it is just not properly explained anywhere in their
docs, I had to find a french comment mentioned in an <a href="https://github.com/FreshRSS/FreshRSS/issues/785">GitHub thread</a>, so I used
<a href="https://deepl.com">DeepL</a> to translate it and, it was actually not that hard
to do, but I decided to explain it a bit more here.</p>

<h1 id="the-proper-tutorial">The proper tutorial</h1>

<p>Open any article from any website that doesn’t let you fetch full, content,
I’ll go with <a href="https://www.androidpolice.com/2020/05/09/android-police-is-now-on-the-mastodon-social-network/">this random article</a>.</p>

<p>Now, in your browser find a way to open the HTML source code of such website.</p>

<p>Here, everything will depend on the site’s structure, but it should contain a
main <code class="language-plaintext highlighter-rouge">body</code> or <code class="language-plaintext highlighter-rouge">article</code> HTML element, which has the important stuff inside of
it. You should be able to find some id or class that makes it easy to
recognize.</p>

<p>In the case of Android Police, we have this line:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&lt;section id="article-body" class="article-body" itemprop="articleBody"&gt;
</code></pre></div></div>

<p>Now, we can go to the management settings of the feed we want, and scroll to
the bottom to the Advanced section, there, you should see an option named
<code class="language-plaintext highlighter-rouge">Article CSS selector on original website</code>. There, you will input the class or
id of the HTML element containing the article content. If you got an id, you
should input <code class="language-plaintext highlighter-rouge">#idname</code>, if its a class, you use <code class="language-plaintext highlighter-rouge">.classname</code>, note the use of
the <code class="language-plaintext highlighter-rouge">#</code> and <code class="language-plaintext highlighter-rouge">.</code> to differentiate them. You can see how it would look here:</p>

<figure class="img">
  <picture>
    <source srcset="/assets/img/blogs/2022-01-11-fetch-article-freshrss-css-setting.webp" type="image/webp" />
    <source srcset="/assets/img/blogs/2022-01-11-fetch-article-freshrss-css-setting.jpg" type="image/jpeg" />
    <img class="mx-auto" src="/assets/img/blogs/2022-01-11-fetch-article-freshrss-css-setting.jpg" alt="" />
  </picture>
  </figure>

<p>If the site is super simple or classless, you might want to go with the HTML
element itself, or a sequence of nested elements, such as <code class="language-plaintext highlighter-rouge">main body</code>, its all
up to the site, so make sure to check properly.</p>

<p>Finally, scroll to the bottom of the settings and click the “Reload articles”
button, to fetch everything again, now you should see the full content instead
of just whatever small portion of text is included in the default feed.</p>

<p>This is how Simon’s website posts look now on my feed:</p>

<figure class="img">
  <picture>
    <source srcset="/assets/img/blogs/2022-01-11-fetch-content-rss-final-result.webp" type="image/webp" />
    <source srcset="/assets/img/blogs/2022-01-11-fetch-content-rss-final-result.jpg" type="image/jpeg" />
    <img class="mx-auto" src="/assets/img/blogs/2022-01-11-fetch-content-rss-final-result.jpg" alt="" />
  </picture>
  </figure>

<p>As you can see, some sites will have small problems like duplicate titles or
maybe even a couple ads showing up in there, but hey, its the full article
instead of some summary that requires me to click one more time. Yes, you might
need to do this whole process with every site you follow that doesn’t have full
content in their feeds, but its kinda cool, maybe FreshRSS will add an easier
way to do this soon enough.</p>

<p>So, this is the 79th post for <a href="https://100DaysToOffload.com">#100DaysToOffload</a>
challenge, thanks again for the inspiration Simon.</p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="tutorial" /><category term="rss" /><category term="foss" /><category term="selfhost" /><summary type="html"><![CDATA[So, some blogs and sites I follow don't want to display full articles in their RSS feed... fine, I'll do it myself, and also teach you!]]></summary></entry><entry><title type="html">Selfhosting my news feed with FreshRSS</title><link href="https://joelchrono.xyz/blog/self-hosting-my-news-feed-with-freshrss/" rel="alternate" type="text/html" title="Selfhosting my news feed with FreshRSS" /><published>2022-01-01T07:00:00-06:00</published><updated>2022-01-01T07:00:00-06:00</updated><id>https://joelchrono.xyz/blog/self-hosting-my-news-feed-with-freshrss</id><content type="html" xml:base="https://joelchrono.xyz/blog/self-hosting-my-news-feed-with-freshrss/"><![CDATA[<p>So, I have been using Miniflux for the last few months, and it has worked quite greatly. However, I was not self-hosting it myself, and, while I could just keep using it, since there was no problem for my provider, I decided that, since I was already self-hosting Nextcloud, I could try installing their News add-on. Except that there was a small detail…</p>

<p>You see, I am running RaspberryOS 32bit, and for some reason, the News extension for Nextcloud needs a 64bit operating system. So, instead of being clever and changing distro since I will have to do it one day anyway, I just decided to install something else.</p>

<p>At first I wanted to go for Miniflux, since I was already using it, but then I remembered that it required a Postgres database, and while I don’t really have anything against it, I already had MariaDB installed, and I did not felt like having multiple database formats running on my device.</p>

<p>I considered going for TT-RSS or FeedBin but I ultimately went with FreshRSS since it seemed to be the easiest to set up, at least from what I saw.</p>

<p>I initially git cloned the latest release, configured a database and user for FreshRSS and ultimately did the setup with the web interface. Sadly, I was getting a weird <code class="language-plaintext highlighter-rouge">Error during context user init!</code> message once everything was supposedly alright.</p>

<p>There was no similar problems online, but I decided to go back one version and instead of git I downloaded the tarball. I kept everything unchanged, and it worked just fine. I realized I can actually update FreshRSS via the web interface, and I it seems to have worked when I did it.</p>

<p>So yeah, I have now switched to a self-hosted RSS provider, and it is actually quite great, I still have to find a good theme tho, since the available dark theme kind of sucks, at least for my taste.</p>

<p>I am still probably going to move to a 64 bit distro, so I’ll keep you updated on that.</p>

<p>This has been day 72 of <a href="https://100DaysToOffload.com">#100DaysToOffload</a></p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="foss" /><category term="tutorial" /><category term="linux" /><category term="raspberrypi" /><category term="selfhost" /><category term="rss" /><summary type="html"><![CDATA[So, I decided to take a look at FreshRSS and try and install it by myself on my Raspberry Pi]]></summary></entry><entry><title type="html">How I use RSS</title><link href="https://joelchrono.xyz/blog/rss-usage/" rel="alternate" type="text/html" title="How I use RSS" /><published>2021-02-06T00:00:00-06:00</published><updated>2021-02-06T00:00:00-06:00</updated><id>https://joelchrono.xyz/blog/rss-usage</id><content type="html" xml:base="https://joelchrono.xyz/blog/rss-usage/"><![CDATA[<h1 id="why-rss---">Why RSS?  💻 📱</h1>

<p>Websites of today are bloated, if you are reading this, you probably know that. If I want to access information from any article, I also have to deal with sidebars full of suggestions, ads and images that I don’t care about, and only try to keep me browsing and wasting my time.</p>

<p>Due to me trying to use the Internet on a more meaningful way, I decided to get most of my text based content, and even videos from Youtube, LBRY or other sites, fetched into a single place that shows me every article I need, this is the biggest strength of the Really Simple Syndication feed.</p>

<h2 id="️-rss-really-simple-setup">🗒️ RSS: Really Simple Setup</h2>

<p>I have seen a bunch of different ways that people use to sync their feeds, be it with services like Feedly or Inoreader, or just copying and pasting their OPML files. Accordingly, there are a lot of programs and websites that allow you to access your feed, be it minimal, terminal based and with no images, or full featured, offering diverse layouts and customization options.</p>

<p>I have checked many of those programs, but I am going to show you my current choices both for my Android device and my Linux computer</p>

<h3 id="flym"><a href="https://github.com/FredJul/Flym">Flym</a></h3>

<p>This is my current choice for android devices. It is completely open source and quite simple to use. It is fairly functional, and I love that it can fetch full websites, even when their RSS are incomplete.</p>

<p>This is how it’s interface looks like, I have the dark AMOLED theme enabled.</p>

<figure class="img">
  <picture>
    <source srcset="/assets/img/blogs/2021-02-06-flym.webp" type="image/webp" />
    <source srcset="/assets/img/blogs/2021-02-06-flym.jpg" type="image/jpeg" />
    <img class="mx-auto" src="/assets/img/blogs/2021-02-06-flym.jpg" alt="" />
  </picture>
  </figure>

<p>The app allows the creation of groups, which helps to categorize stuff according to your needs. This app has a few caveats tho, since sometimes reloading feeds can be a bit of a chore, but, it mostly works correctly. Flym has the basic exporting and importing features too, so it’s a very nice and tidy application. Time to talk about my desktop feed reader.</p>

<h3 id="newsboat"><a href="https://newsboat.org/">Newsboat</a></h3>
<p>The website sums everything up</p>
<blockquote>
  <p>Newsboat is an RSS/Atom feed reader for the text console. It’s an actively maintained fork of Newsbeuter.</p>
</blockquote>

<p>So, it is a fork the now dead Newsbeuter, and it offers a fairly similar functionality. Being a terminal based reader, it is keyboard driven, and its great at that. The config file is fairly customizable, although I haven’t played too much with it.</p>

<figure class="img">
  <picture>
    <source srcset="/assets/img/blogs/2021-02-06-newsboat.webp" type="image/webp" />
    <source srcset="/assets/img/blogs/2021-02-06-newsboat.jpg" type="image/jpeg" />
    <img class="mx-auto" src="/assets/img/blogs/2021-02-06-newsboat.jpg" alt="" />
  </picture>
  </figure>

<h2 id="-rss-really-simple-to-syncthing">🔄 RSS: Really Simple to Sync<del>thing</del></h2>

<p>Honestly these puns are kind of cringe. Anyways, <a href="https://syncthing.net/">Syncthing</a>, is such a wonderful tool. Ever since I figured out how to use it, I really loved it with all my heart. The same goes to KDE Connect, which, despite it’s name, works on my window manager wonderfully.</p>

<p>The only relatively bad thing is that I have to press “Export” e “Import” (or input the command), but the good thing is, that I will know for sure that I will get the latest OPML I saved.</p>

<p>This a little screenshot that hopefully helps you understand how it works. I can go into more detail in a later blog if you so wish.</p>

<figure class="img">
  <picture>
    <source srcset="/assets/img/blogs/2021-02-06-sync.webp" type="image/webp" />
    <source srcset="/assets/img/blogs/2021-02-06-sync.jpg" type="image/jpeg" />
    <img class="mx-auto" src="/assets/img/blogs/2021-02-06-sync.jpg" alt="" />
  </picture>
  </figure>

<p>Depending on your feed reader of choice, you will have to setup up some things. In my case, I just have an alias for Newsboat in my .bashrc.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">alias </span><span class="nv">syncboat</span><span class="o">=</span><span class="s2">"newsboat --export-from-opml /path/to/opml.opml"</span>
</code></pre></div></div>

<p>And in Flym’s case, well, I can’t do much with it. There are applications that allow you to create shortcuts to certain parts of it. Android has some of this built-in, if you keep pressed the Flym icon on your phone home screen, you can see some shortcuts to open Favorites, Unreads, etc.</p>

<p>Using Nova Launcher, I can have an Activity shortcut, which allows me to do a similar thing, but it is a bit more complicated. Sadly, Flym only has a Main Activity, so no way to import OPMLs from there, I think I can talk about Nova’s Activites later.</p>

<p>As of now, I think it would be nice if the developer added a way to open those files directly from my file manager, be it with the Share menu, or showing up in the Open With options, since I am aware that <a href="https://antennapod.org/">AntennaPod</a>, a podcast app, shows up there. That way, I can just create a shortcut to the folder, or even the file, and it would be easier to setup.</p>

<h1 id="-wrapping-up">💭 Wrapping up</h1>

<p>This is my second blog, in my <a href="https://100daystooffload.com/">#100DaysToOffload</a> challenge. After reading <a href="https://atthis.link/blog/2021/rss.html">Marc’s post</a> about why he is still using RSS, I decided to do my take on the matter. He goes to different places on his blog, so you should check it out too!</p>

<p>Let me know how do you manage your feeds by @ me on <a href="https://fosstodon.org/@joeligj12">Mastodon</a>, maybe you got a better solution to manage your feeds.</p>]]></content><author><name>joelchrono</name><email>me@joelchrono.xyz</email></author><category term="degoogle" /><category term="foss" /><category term="linux" /><category term="rss" /><summary type="html"><![CDATA[How I use RSS to consume websites, youtube, blogs and Internet things]]></summary></entry></feed>